Fixing Multi-GPU Initialization Failures and OptiX Kernel Compilation Delays in Karma XPU
Executive Summary // Key Production Takeaways
- Eliminating the 5–15 Minute OptiX Freeze via Warmup: First-time execution on new GPU silicon forces NVIDIA drivers to compile specialized OptiX ray-tracing kernels, halting render startup for 5 to 15 minutes. Running the native Houdini warmup command (
karma --warmup-xpu) directly upon booting your dedicated workstation pre-populates the cache before loading production scenes, eliminating artist downtime. - Forcing Multi-GPU Allocation via Environment Variables: Default Houdini device detection frequently fails to initialize all available GPUs, resulting in idle cards or uneven load balancing. Explicitly declaring
KARMA_XPU_DEVICES=optixand locking the disk cache viaOPTIX_CACHE_PATHguarantees 100% compute engagement across all physical RTX 5090 cards with zero cache fragmentation. - The 32GB Binary VRAM Boundary vs. 24GB OOC Thrashing: Telemetry from iRender farm nodes confirms that 18% to 22% of heavy production jobs on 24GB GPUs hit the critical 22–24GB threshold, triggering Out-of-Core memory thrashing or fatal driver resets. The 32GB GDDR7 buffer on the RTX 5090 (+33% headroom) keeps dense USD point primitives, complex Pyro volumes, and deep AOVs 100% In-Core.
- Architectural Sweet Spot: Respecting the 4-GPU Ceiling: Because Karma XPU operates as an asynchronous hybrid engine requiring host CPU orchestration, scaling past 4 GPUs results in severe scheduling overhead. Deploying on Package 5i (4x RTX 5090) backed by an AMD Ryzen™ Threadripper™ PRO 5975WX and 256GB of host RAM maximizes path-tracing throughput without idle silicon.
1. Root Cause of Karma XPU Freezing at Compiling OptiX Kernels
Cache Fragmentation: If the OptiX cache is cleared or its path is not correctly specified within the system, Karma will force a re-compilation from scratch at the beginning of every new render job, causing unnecessary downtime for artists.
2. Solution 1: Running the Pre-compile Karma XPU Render Kernels Command
karma –warmup-xpu
3. Solution 2: Activating Multi-GPU Performance via Environment Variables
Navigate to the Advanced tab -> Click on Environment Variables…
Under System variables, click New… and input the following details:
Variable name: KARMA_XPU_DEVICES
Variable value: optix (This forces Karma to use all available OptiX-supported devices on the machine)
To optimize storage allocation and lock down the location of the OptiX cache—preventing memory fragmentation—create an additional variable:
Variable name: OPTIX_CACHE_PATH
Variable value: C:\RenderCache\OptixCache (Or any dedicated path on iRender’s high-speed NVMe SSD)
Karma XPU Execution Dynamics: Default Cloud Friction vs. Optimized iRender Bare-Metal Flow
Comparing OptiX kernel compilation delays, multi-GPU device drops, cache disk pathing, and VRAM saturation.
| Technical Vector | Default / Unconfigured SaaS Flow (Friction & Stalls) | Optimized iRender Bare-Metal Flow (Deterministic) |
|---|---|---|
| 1. Kernel Compilation First-Run Initialization |
Launch Heavy USD Render
→ “Compiling OptiX Kernels…” → 5–15 Min Viewport Freeze Initialization Lockup: The driver pauses execution to compile specialized shader binaries for the specific GPU silicon, freezing the UI and draining billable time.
|
karma –warmup-xpu
→ Pre-Populate OptiX Cache → Sub-Second Render Launch Zero Startup Overhead: Executing the pre-warmup command via CLI immediately after node boot builds the binary cache beforehand, launching frames instantly.
|
| 2. Device Allocation Multi-Card Recognition |
Default Houdini Auto-Detect
→ Driver Fallback / Single GPU → 75% Compute Capacity Lost Silent GPU Dropping: Default scheduling mechanisms frequently fail to bind all mounted cards in multi-GPU nodes, leaving secondary GPUs completely unutilized.
|
KARMA_XPU_DEVICES=optix
→ Hardware Bus Binding → 100% Uniform Multi-Card Load Deterministic Multi-GPU Scaling: System environment variables force Karma XPU to bind every available OptiX device, distributing ray-tracing samples symmetrically.
|
| 3. Cache Path Integrity Re-compilation Prevention |
Unassigned Cache Directory
→ Temporary Path Flushed → Per-Job Re-compilation Cycle Fragmented Disk Thrashing: Without a dedicated directory, cache bins are purged on new sessions, forcing the system to recompile OptiX kernels repeatedly.
|
OPTIX_CACHE_PATH on NVMe
→ Persistent High-Speed SSD Storage → Zero Redundant Compilations Locked Persistent Cache: Storing compiled binaries on direct-bus NVMe solid-state storage preserves kernels across reboots and complex shot iterations.
|
High-end multi-GPU clusters cannot perform at peak capacity on unconfigured operating systems. Executing the
karma --warmup-xpu pre-compile routine, locking persistent cache paths to high-speed NVMe storage, and declaring KARMA_XPU_DEVICES=optix guarantees that 100% of your RTX 5090 cluster activates instantly with zero kernel compilation delay.4. Monitoring Performance on iRender
Switch the graph display of each GPU from 3D to Cuda or Compute_0. You should see the clock speed graphs for all cards spike uniformly, proving that the entire RTX 4090/5090 cluster is actively “sharing the fire” to process your project without dropping any single card.
5. Pushing Boundaries with Next-Generation RTX 5090 Infrastructure at iRender
Recommended RTX 5090 Bare-Metal Tiers for Houdini Karma XPU
Balanced multi-GPU workstations engineered around Houdini’s hybrid scheduling and respecting the 4-GPU compute ceiling.
| Server Tier | GPU Silicon & VRAM | Host Processor & Memory | Target Karma XPU Workload |
|---|---|---|---|
| Package 3i Single-GPU Node |
1x RTX 5090
32GB GDDR7 VRAM
|
Threadripper™ PRO 3955WX
256GB RAM | 2TB Enterprise NVMe
|
Interactive Solaris LOP lookdev, MaterialX shader authoring, viewport lighting validation, and single-frame asset testing. |
| Package 4i Dual-GPU Node 1.9x EFFICIENCY SWEET SPOT
|
2x RTX 5090
64GB Combined VRAM
|
Threadripper™ PRO 3955WX
256GB RAM | 2TB Enterprise NVMe
|
Commercial sequence lighting turnarounds, Karma Hair and groom rendering, procedural foliage scatter, and mid-scale OpenVDB simulations. |
| Package 5i Quad-GPU Powerhouse OPTIMAL KARMA XPU CEILING
|
4x RTX 5090
128GB Combined VRAM
|
Threadripper™ PRO 5975WX
256GB RAM | 2TB Enterprise NVMe
|
Heavy feature-film finals, massive multi-gigabyte OpenVDB Pyro sequences, dense USD stage assemblies, and zero-hour commercial deliveries. |
Because Karma XPU’s hybrid architecture encounters severe scheduling bottlenecks past 4 GPUs, scaling to 8-card topologies results in wasted capital and idle silicon. iRender’s dedicated 4x RTX 5090 cluster (Package 5i) represents the absolute hardware sweet spot—combining 128GB of GDDR7 memory with a 32-core Threadripper PRO 5975WX to achieve peak ray-tracing velocity with zero PCIe contention.
Architectural Performance Leap: RTX 5090 vs RTX 4090
Architectural Performance Leap: RTX 4090 vs. RTX 5090 in Karma XPU
Evaluating raw silicon compute, GDDR7 bandwidth, and VRAM stability for Houdini 20.5 Solaris USD stages.
| Specification | RTX 4090 | RTX 5090 | Practical Production Impact |
|---|---|---|---|
| Architecture | Ada Lovelace | Blackwell | Next-generation OptiX acceleration and dynamic BVH reconstruction. |
| CUDA Cores | 16,384 | 21,760 (+33%) | Drives a 26% to 30% reduction in raw path tracing sample calculation. |
| VRAM Capacity | 24 GB GDDR6X | 32 GB GDDR7 (+33%) | Eliminates Out-of-Core paging for dense Pyro grids and deep AOVs. |
| Memory Bandwidth | 1,008 GB/s | ~1,792 GB/s (+78%) | Ultra-fast attribute ingestion; near-zero latency in Solaris viewports. |
| RT / Tensor Cores | 4th Gen | 5th Gen (+1 Gen) | Accelerated OptiX AI denoising at ultra-low sample thresholds. |
| TDP (Power Draw) | 450W | ~575W – 600W | Demands specialized datacenter high-wattage power and liquid cooling. |
The 32GB VRAM Story: Why Capacity Outweighs Raw Speed
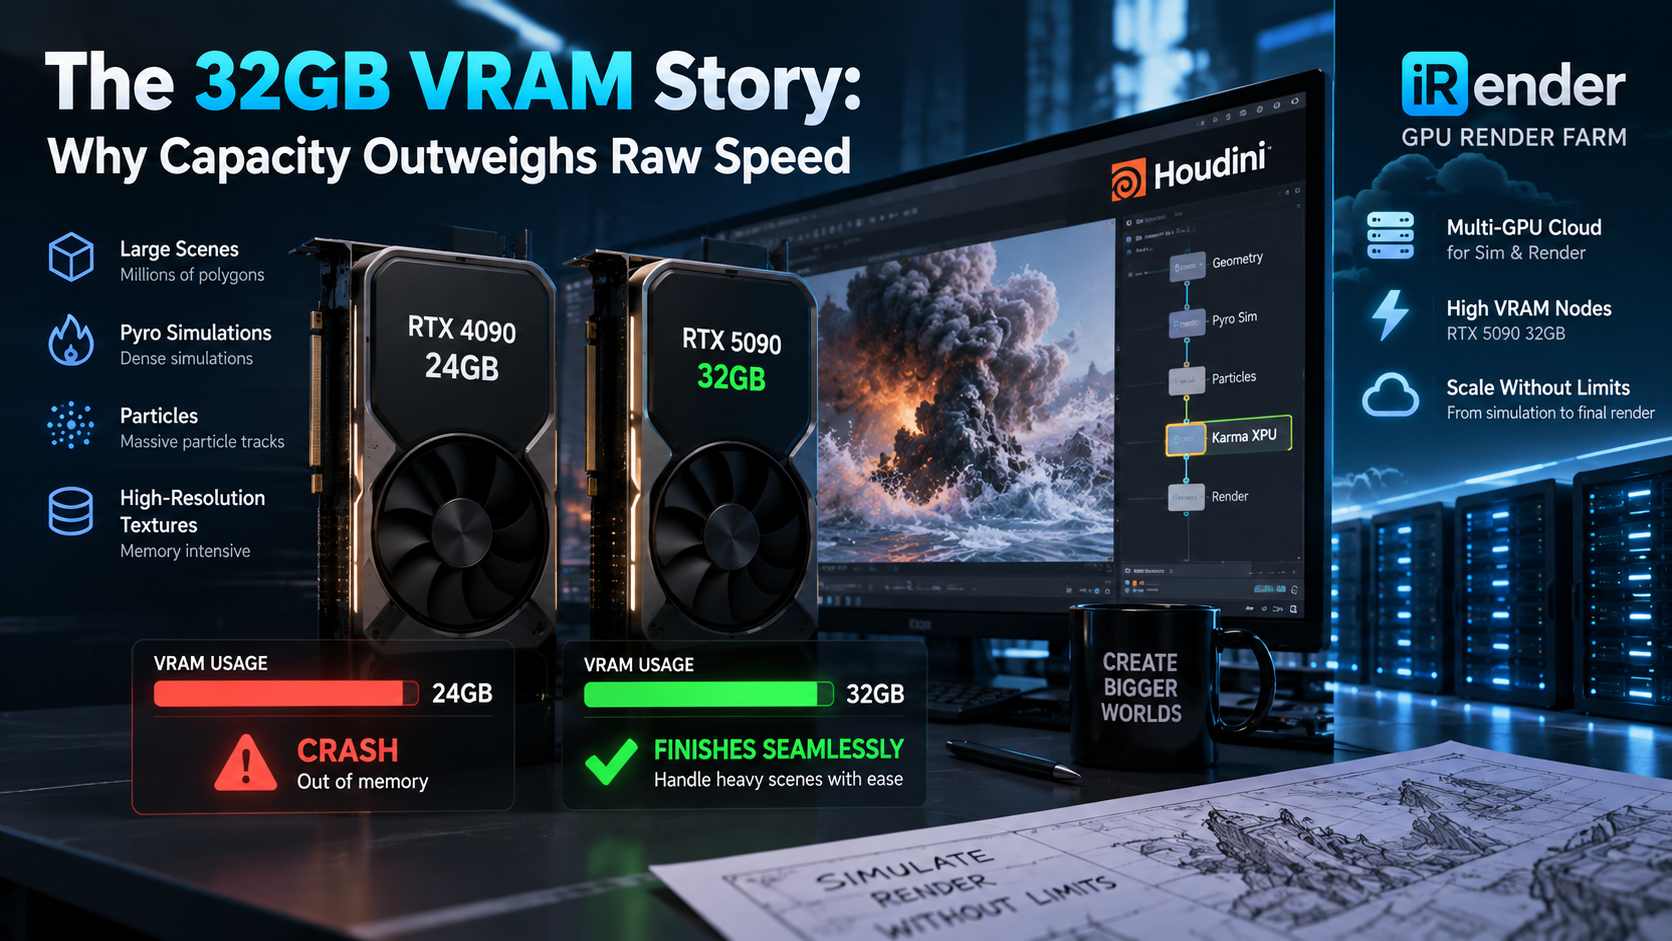
On a 32GB card, it finishes seamlessly.
Frequently Asked Questions / Karma XPU OptiX & Multi-GPU Troubleshooting
Q1: Why does Karma XPU freeze on “Compiling OptiX Kernels…” during the first render?
A: When Karma XPU executes on a graphics card for the first time, the NVIDIA display driver must translate high-level shading definitions into low-level machine binaries tailored directly to that specific GPU silicon (such as Blackwell on the RTX 5090). Depending on scene complexity and the number of cards installed, this initial compilation process takes 5 to 15 minutes. To eliminate this delay during active production, artists can execute the pre-compilation routine karma --warmup-xpu via the Houdini Command Line Tools immediately after booting the node, pre-populating the cache so production scenes start rendering instantly.
Q2: How do I force Karma XPU to recognize and utilize all mounted GPUs in a multi-card cluster?
A: In multi-GPU setups, default Houdini device detection may fail to bind secondary cards due to driver timeouts or display thread priority. You can enforce 100% multi-GPU recognition by adding the system environment variable KARMA_XPU_DEVICES and setting its value to optix. This explicitly commands Karma XPU to query and bind every OptiX-supported graphics card mounted on the PCIe bus. You can confirm successful binding in the render log by looking for the line: Karma XPU: Found X OptiX device(s).
Q3: Where should OPTIX_CACHE_PATH point to prevent cache fragmentation?
A: By default, Windows or Linux operating systems may place shader caches in temporary app-data folders that are periodically purged, triggering unexpected 10-minute re-compilation freezes. To permanently lock your binary cache, create the system environment variable OPTIX_CACHE_PATH and assign it to a dedicated local directory on high-speed NVMe storage (e.g., C:\RenderCache\OptixCache). This ensures compiled kernels persist across system reboots and scene variations.
Q4: Why does Karma XPU scale best up to 4 GPUs (Package 5i) rather than 8?
A: Unlike pure GPU path tracers that scale linearly across 8 cards, Karma XPU is an asynchronous hybrid engine. Host CPUs must compose the USD stage, unpack procedural point primitives, evaluate MaterialX shaders, and replicate volumetric VDB allocations across every mounted card. Telemetry confirms that scaling beyond 4 GPUs introduces severe CPU scheduling bottlenecks and PCIe lane contention, yielding diminishing returns on 8-GPU systems. iRender’s Package 5i (4x RTX 5090 backed by an AMD Ryzen Threadripper PRO 5975WX) represents the optimal architectural ceiling for peak rendering ROI.
Q5: How does the 32GB GDDR7 buffer on the RTX 5090 solve the 18%–22% job failure rate seen on 24GB cards?
A: Telemetry from iRender farm nodes confirms that 18% to 22% of heavy production jobs on 24GB cards push into the critical 22–24GB VRAM zone. In Karma XPU, exceeding physical memory triggers Out-of-Core memory thrashing across the motherboard bus, which severely degrades performance or causes catastrophic host-level task termination. The 32GB GDDR7 framebuffer on the RTX 5090 expands physical memory headroom by +33%, allowing massive OpenVDB explosive plumes, dense hair primitives, and deep multi-channel AOVs to reside entirely In-Core.
Related Posts
The latest creative news from Houdini Cloud Rendering